You walk into the debrief and two interviewers have rated the candidate’s communication, one a 4 and one a 2, and neither wrote down what the candidate said. The competency the hiring manager insisted on at intake was never assigned to an interview, so it went unasked. Every interview scorecard in the loop was submitted on time, and the room still can’t decide.
I’d build the scorecard backwards from that meeting. Before the first interview, agree which competencies the hire turns on and what each rating means for this role. Assign each competency an owner in the loop, then have each interviewer write their evidence and lock their card before anyone hears the others.
Skip those choices and the hiring manager spends the debrief collecting evidence that should have arrived on the cards, then books another interview to settle the competency that went untested.
Why scorecards slow the hiring decision down.
A scorecard that holds up the decision usually fails in one of four places, and each one surfaces at the debrief as a question the cards can’t answer.
- A competency means something different to each interviewer, so a 4 and a 2 can rest on the same answer.
- A must-have was never given to a particular interview, so each interviewer assumed a colleague had covered it.
- Ratings were written after the interviewers had talked to each other, so the cards repeat the loudest opinion in the loop.
- The card ends on an overall hire or no-hire. A strong impression on one competency then covers for a gap on another, and the hiring manager can’t see which happened.
An interviewer who completes a card like that is using the form as it was designed, so each of these is a problem with the form. A reminder email gets the form submitted sooner and leaves all four problems on it.
Build the interview scorecard backwards from the debrief.
Start from the meeting where the hire gets decided and ask what the hiring manager needs in front of them to decide it without reopening the interviews. The six steps below answer that in the order you’d take them, from intake to the morning of the debrief.
Pick the competencies the decision turns on.
Write the list with the hiring manager at intake and put each competency through one test: if a candidate failed this one and passed everything else, would you still make the offer? If the answer is yes, it’s a nice-to-have. Leave it off the card, or give it a notes line with no rating attached.
Then mark the competencies where a low rating ends the process. A card that averages its ratings lets a strong showing on communication buy back a weak one on the work the role exists to do, and the debrief ends up arguing about an average.
I’d rather see four competencies with a real question behind each than nine that each get a passing mention.
Anchor the scale with two lines per competency.
A bare scale invites every interviewer to bring their own bar. Under each competency, write one line for the low rating and one for the high rating, in terms an interviewer could hear in an answer.
For a product manager hire, that might read: “Stakeholder management. 2: describes keeping people informed. 4: names a stakeholder who disagreed, what she did about it, and how the decision landed.” That’s enough to start calibrating, and the gaps show up the first time two interviewers rate the same answer differently.
A fuller version, with a line for every point on the scale, is laid out in this interview scorecard template. Copy its structure even if you rewrite every competency in it.
Give every competency an owner in the loop.
Map competencies to interviews before anyone is booked. Each interviewer gets one or two competencies to probe properly, and each competency gets an interview that’s responsible for it. The must-haves get a second read, so the decision never rests on one person’s view of the competency that can end the process.
Below is the map for the same product manager hire. The columns are the part to keep, since your competencies will differ.
| Competency | Must-have | Owned by | Second read |
|---|---|---|---|
| Product judgment | Yes | Product case interview | Hiring manager interview |
| Stakeholder management | Yes | Hiring manager interview | Cross-functional interview |
| Working with engineers | No | Cross-functional interview | None |
| Motivation for the role | No | Recruiter screen | None |
The map also tells each interviewer what to leave alone. An interviewer who knows the recruiter screen owns motivation can spend their hour on product judgment and leave the other competencies to their owners.
Ask for the evidence before the rating.
Order the fields so the interviewer writes down the candidate’s answer before choosing a number. Written in that order, the rating has to fit the evidence. In the reverse order, the evidence gets picked to support a number the interviewer had already settled on.
One or two sentences per competency does it: the answer, close to the candidate’s words, and what it showed. “Walked through the roadmap cut she argued against and lost, and what she shipped instead” lets a hiring manager check a 4 on stakeholder management. “Good with stakeholders” gives them nothing to check.
If the applicant tracking system (ATS) your team uses can mark a field as required, mark the evidence field.
Limit the recommendation to what the interviewer owned.
Most scorecards end on an overall hire or no-hire, and most interviewers answer it after one conversation that covered one or two competencies. Ask instead whether the candidate met the bar on the competencies that interviewer was given, with a sentence on why. Add “not tested” as an answer for a competency the conversation never reached.
The overall call belongs to the hiring manager, who is the one person reading every card. And “not tested” is a useful answer to get: it shows the gap in the loop while there’s still time to book a conversation that closes it.
Have every card submitted before anyone compares notes.
Tie the deadline to the debrief: every card is in before the meeting opens, and each interviewer reads a colleague’s card only after submitting their own. A card written after hearing the panel talk is a second copy of the panel’s view. Cards locked first give the hiring manager separate reads to compare, and a split between two of them becomes information to work through.
At the debrief, take the must-haves in turn. Read every rating and its evidence on the first one and settle whether the candidate cleared it before moving to the next. Run in that order, a debrief can end early, because once a must-have comes back below the bar on both of its reads, the decision is made.
Running the rest of that meeting is covered in this guide to running the debrief itself.
What fairer means on a scorecard.
Every candidate for the role meets the same competencies against the same written bar, and every interviewer rates before hearing the others. On a scorecard, that procedure is what fair means, and it covers less than the word suggests.
A scorecard can hold the process steady from candidate to candidate. It doesn’t show whether a competency was the right thing to measure, and it can’t stop an interviewer from asking one candidate harder questions than the next. Both of those live in the questions, which the card never sees.
So I’d check the questions too. Take two candidates for the same role and count the questions each interview asked on each competency. If one candidate got five questions on a must-have and another got one, their ratings on it can’t be compared, however carefully the card was built.
Where Metaview fits in interview scorecards.
Writing the evidence is the step I’d expect to take longest, because it asks an interviewer to hold an answer close to word for word while still running the interview. That’s the part Metaview can take on. Every rating and the recommendation remain the interviewer’s.
Metaview’s Notetaker records and transcribes the conversation as a visible participant in the interview, then produces structured notes from it. Nothing has to be written down live once the Notetaker’s recording captures every spoken word, which leaves the evidence box free to quote the candidate directly from the record. A hiring manager who questions a rating can also go back to the answer behind it.
The Notetaker also writes a first draft of the scorecard, built from that conversation. The interviewer reviews the draft and sets each rating before submitting it. Submission goes straight into the ATS for Ashby and Lever, while for Greenhouse the interviewer pastes it in. In Ashby and Greenhouse, a Metaview browser extension can autofill a scorecard’s objective sections, while the subjective fields stay blank for the interviewer and the hiring recommendation is theirs to complete, which under this method means the call on the competencies they owned. The integrations page lists the current options for each ATS.
Notes follow a template, which you can customize to the structure of each interview. I’d build it from the scorecard’s competency names, so the notes and the card use the same words. The illustration below, from a section Metaview has used on its website, shows a template being chosen for a screening call.
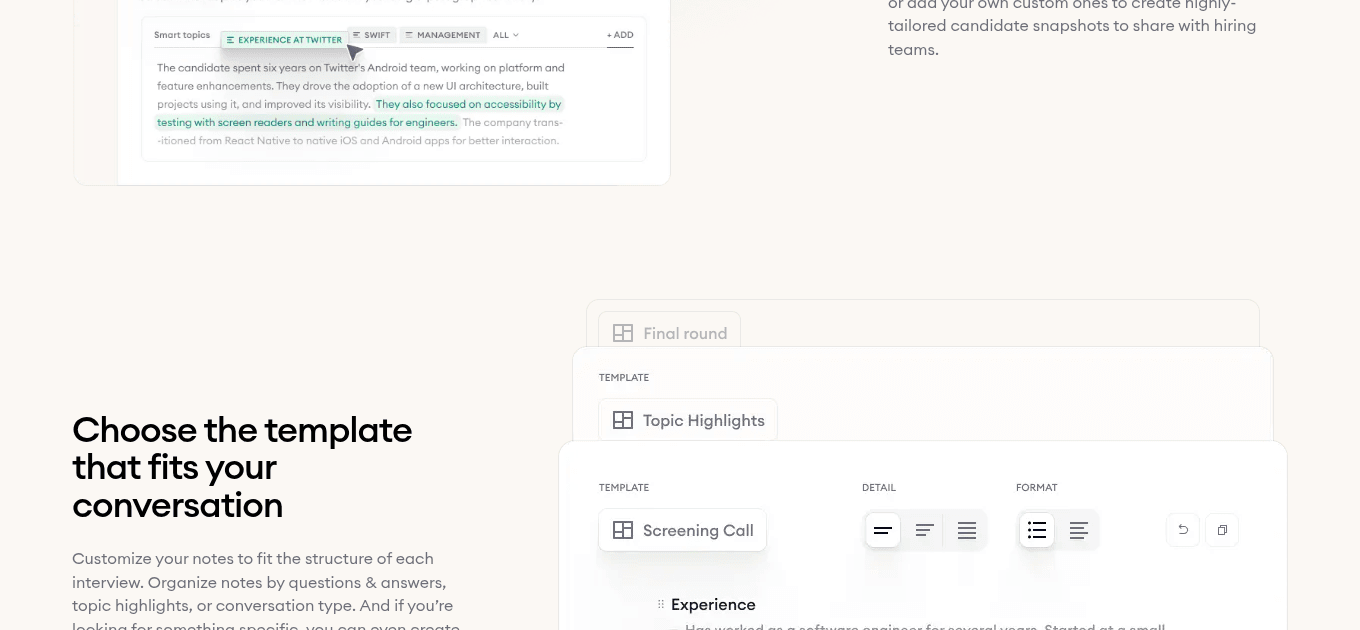
- 1The template chosen for this conversation, “Screening Call.”
- 2Other templates waiting behind it, “Topic Highlights” and “Final round.”
- 3The “Detail” and “Format” settings, which change how long the notes run and how they’re laid out.
A loop needs more than one template, because a hiring manager interview and a debrief call carry different headings. In the capture below, also from Metaview’s site, each template is paired with a kind of call, and some with a role.
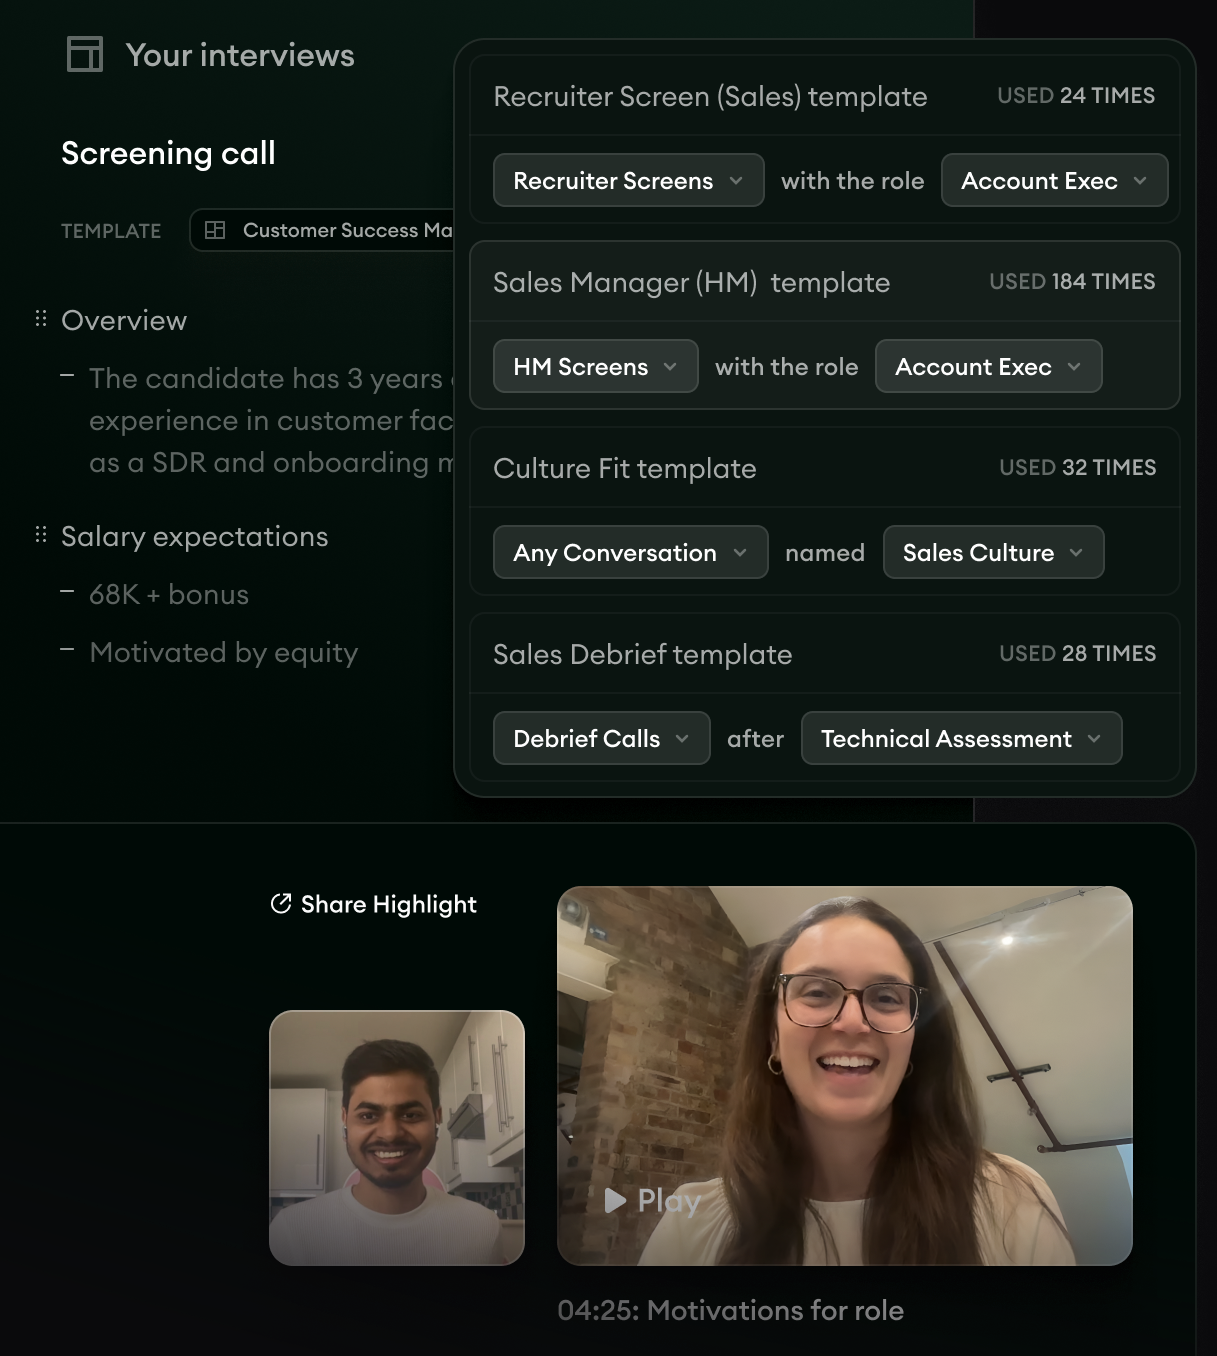
- 1A hiring manager screen with its own template, “Sales Manager (HM),” set for the role “Account Exec.”
- 2A separate “Sales Debrief” template for debrief calls held after a technical assessment.
- 3One screening call’s notes, opening on an “Overview” heading.
The question count from the fairness section is the check I’d least want to do by hand. Metaview Reports works on your organization’s interview data and lets you compare question coverage across interviewers and roles. The illustration below, which Metaview has used to show Reports, lays that count out for one role.
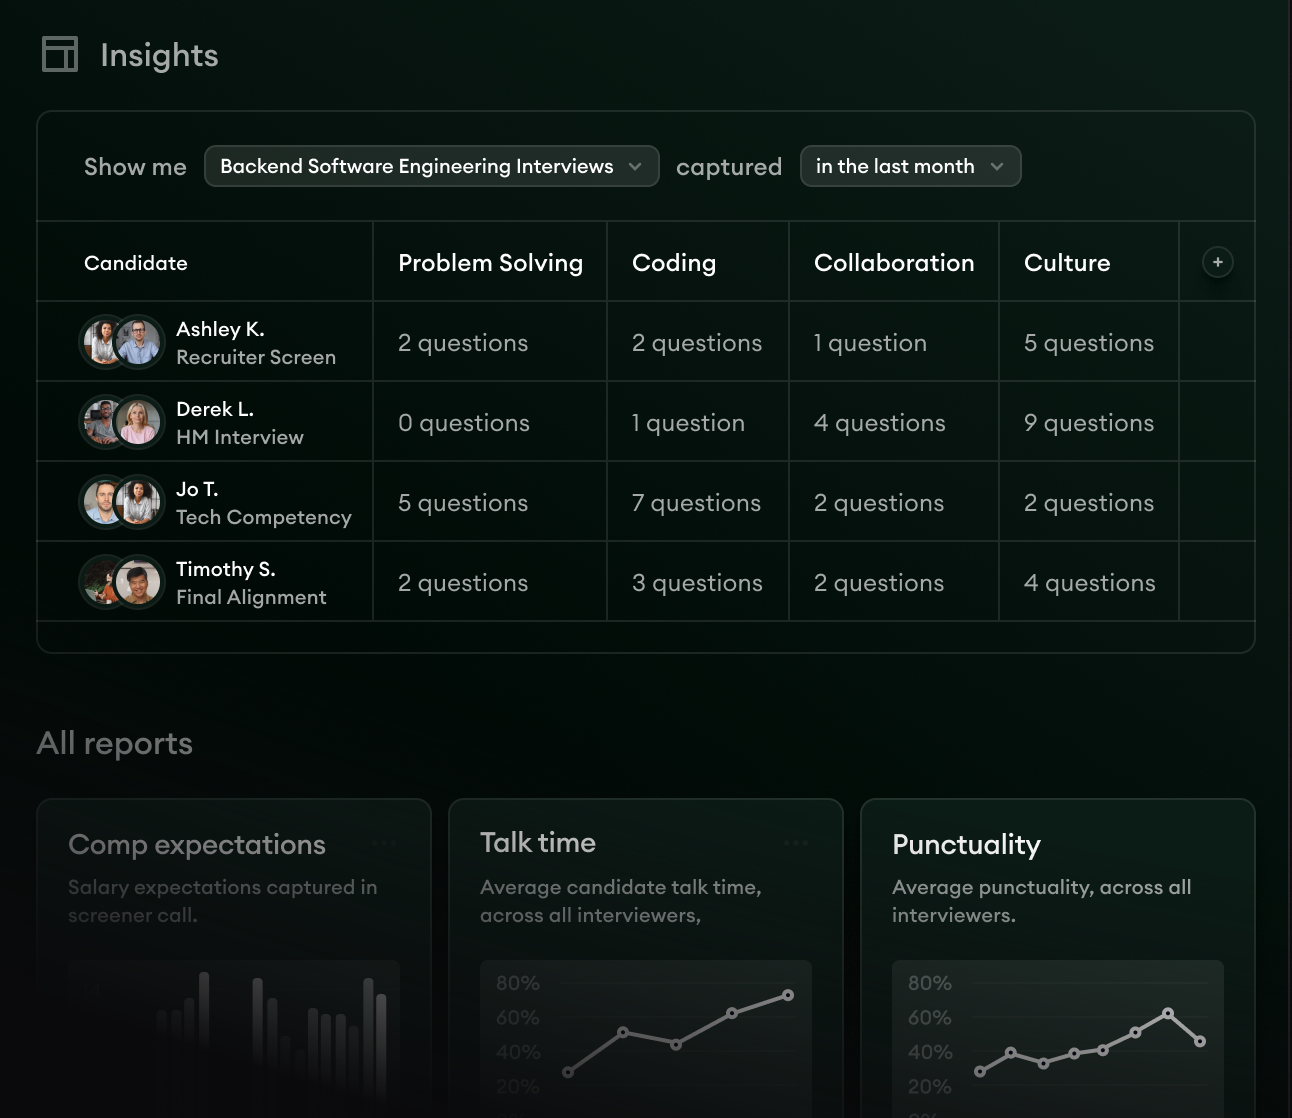
- 1The filter that sets which interviews are counted, here one engineering role over the past month.
- 2One column for each competency the role is assessed on, four in this example.
- 3“0 questions” on “Problem Solving” in Derek L.’s “HM Interview,” a competency that conversation never reached.
If one interview keeps coming back at zero on a competency it owns, fix that interview’s questions before you touch anyone’s ratings. The cards themselves deserve the same scrutiny as the questions. Shahriar Tajbakhsh put that review inside the debrief in his own guide to writing scorecards. He is a Metaview co-founder and its Chief Technology Officer.
The debrief is a great opportunity for hiring managers to give feedback on the quality of the scorecards and note what was helpful or not in informing the ultimate decision.”
The checks below turn that feedback into named steps, so the hiring manager can say which step let a card down.
Run these checks after your next debrief.
Each check below uses the scorecards from one finished debrief, and says which step of the method to repair when it fails.
| Check | What failing looks like | Fix first |
|---|---|---|
| Decision from the cards | The hiring manager can’t state the outcome until the interviewers have talked it through | The recommendation, limited to what each interviewer owned |
| Must-haves covered | A must-have has fewer than two cards with evidence on it | The ownership map |
| Cards in on time | Cards arrived after the debrief had started | The deadline, tied to when the debrief opens |
| Shared meaning | Two cards give different ratings on much the same evidence | The written line under that rating |
| Evidence present | A rating with nothing written beside it | The field order, with the evidence box above the rating |
I’d run the first check before the others, because it tests the whole method at once. When the hiring manager can decide from the cards alone, the debrief becomes a short confirmation, and the same written bar sits under every rating for every candidate.
Check each loop against its scorecard.
Compare question coverage between the interviewers and roles in your own organization’s interview data.
Frequently asked.
What rating scale should an interview scorecard use?
I’d use a four-point scale with no middle option, because it makes every interviewer lean one way on each competency. Whatever the scale, keep it identical across the loop’s interviews and write down what its top and bottom points mean for the role, or the ratings can’t be compared.
Who should own the interview scorecard: recruiters or hiring managers?
The hiring manager owns the competencies and what each rating means, because they’re setting the bar for their own team. The recruiter owns the form around them: who covers which competency, and the deadline that gets every card in before the debrief.
Can one scorecard work for every interview in the loop?
Keep one set of competencies and one scale for the role, and give each interview only the rows it owns. Hand the recruiter screen only the row or two it owns, so its ratings go deep on those.
Can an interviewer change a rating after reading the other scorecards?
Leave the submitted rating as it is and have them say what changed their mind in the debrief, with the evidence that moved them. The hiring manager then sees both the first read and the reason it shifted, which a card edited after the fact would hide.
What should you do with a scorecard that comes back without evidence?
Send it back before the debrief with one question: what did the candidate say that put the rating there? If the interviewer can’t answer, count that competency as not tested for this candidate and decide whether the gap needs another conversation.
