By the fourth interview of a long day, the notes start to change. “Stronger than this morning’s candidate.” “Not as sharp as the last one.” The rating written under those lines measures the distance between two people, and the rubric the panel agreed at intake has stopped being the bar.
That is contrast bias in interviews: each candidate judged against whoever came before them, with the role’s rubric pushed to one side. It runs in both directions. A solid candidate who follows a standout reads as weak, and an ordinary one who follows a poor interview reads as strong, so the same answer can earn two different ratings depending on where it fell in the day.
Comparing is how anyone reads quickly, and a tired panel will do it whatever the bias training said, so I’d work on where the comparison is allowed to happen. Each score describes one person, written before anyone else is in view. When a candidate shows the bar was set wrong, I’d change the bar on purpose and re-read everyone against it. Candidates still get compared, once, when the decision is made.
How contrast bias in interviews gets into a score.
A rubric describes each level in words, and words take effort to apply at the end of a long day. The candidate from an hour ago is vivid by comparison, so the mind reaches for them as the measure, and it does so without saying so.
It bites hardest where one kind of interview runs back to back for one role, such as a day of final rounds or a recruiter working through a stack of first screens. The person most recently in front of the interviewer was asked the same questions as the person being scored, which is exactly what makes the comparison feel fair.
A middle rating written as “weaker than the last one” tells the hiring manager where the candidate sat in the day, and nothing about whether they can do the work the rubric describes. Nothing on the form shows which of the two was measured, so the debrief inherits the queue.
Several other biases creep into interview scoring as well, and there’s a longer read on reducing interviewer subjectivity across the whole process.
Catch the comparison in the words.
The first place contrast shows is the language of the note, so that is where I’d look before touching anyone’s calendar. A rating sentence that names another candidate, or leans on a comparative with no rubric line attached, is measuring a gap.
| What the note says | What it is measured against | The rubric version |
|---|---|---|
| “Sharper than this morning’s candidate.” | The morning’s candidate | “Walked through the trade-off in their last migration and named what they would cut first.” |
| “Not as strong as the first person today.” | The first interview of the day | “Described what the project delivered, but not which decisions on it were theirs.” |
| “Best I’ve seen for this role.” | Everyone interviewed so far | “Met the stakeholder management line with two examples, one where they lost the argument.” |
| “Fine, after that last call anything looks good.” | The weaker interview before it | “Answered the system design question at the level the rubric sets for this role, and went no further.” |
Ask the interviewer to rewrite each comparative in two parts: the rubric line, and what this candidate said or did against it. I’d ask for it every time a comparative turns up in a debrief, until interviewers write the rubric version before anyone has to ask.
If the rubric version is hard to write, that tells you something too. The view came from the comparison and the evidence is thin, so I’d leave the rating open until someone can point at what the candidate said.
If the rubric’s levels are too vague to write against, rewrite them before the next slate. A separate post covers writing rubric levels that an interviewer can point at.
Score each candidate with only their notes open.
Contrast needs two candidates in view at once, so when the scorecard gets written decides whether it can happen.
A scorecard written straight after the interview, from that interview’s notes alone, has one candidate in it. One written after the last interview of the day, covering every candidate the interviewer met, has all of them, and the form turns into a ranking whether anyone meant it to or not.
So I’d set one rule: one candidate open at once. Have each interviewer submit the scorecard before their next interview for the same role, working from their notes on that candidate alone, and hold off rereading anyone else’s scorecard until their own is in. Where the calendar leaves no room for that, book the room: a slot that ends with the scorecard submitted is part of the interview, and I’d put it in the calendar that way.
The same rule covers a panel. When one interviewer’s rating is visible before the next has written theirs, the first rating becomes the bar for the second, which is contrast between interviewers on a single candidate. Keep each panel member’s scorecard out of the others’ view until everyone has submitted.
Panels bring questions of their own, from who asks what to how the room reaches a decision. A post on panel interview practice takes those on.
Change the bar on purpose when a candidate moves it.
A standout candidate can teach the panel something real. They can show the hiring manager that the bar was set too low, or that a line of the rubric asks for the wrong thing entirely.
The damage comes when that lesson changes the bar without anyone saying so. The standout becomes the private measure for everyone interviewed after them, while everyone before was scored against the old rubric. The slate ends up judged on two bars that share a name.
When that happens, I’d pause the slate until the bar changes in writing. Ask the hiring manager to edit the rubric line and say what changed and why, then re-read the earlier candidates against the new version before anyone compares them. If the change can’t be written as a rubric line, the comparison was doing the talking, and the old bar stands.
Hold the side-by-side for the decision.
Candidates do get compared in the end, and that comparison belongs in one place: the decision, after each of them has been discussed alone.
So I’d run the debrief candidate by candidate. Open each discussion on that candidate’s submitted scorecards, and have everyone read them before anyone speaks. I’d also break the order the interviews ran in, because the order of discussion builds a queue of its own, and whoever is discussed first sets the tone for the second. Starting with the candidate the panel split on most is one way to break it.
Once every candidate has been discussed against the rubric, put the scorecards side by side and decide. Comparing candidates belongs here, and by now it runs on ratings that were each written about one person.
Where Metaview fits in scoring one candidate at a time.
Writing the scorecard straight after the interview is the habit this method leans on hardest, and the Metaview Notetaker sits inside that interview. Anyone on the call can see it there as a participant, and it transcribes the conversation as it records. It records only where the interviewer and the candidate have each agreed to be recorded, an agreement that is the hiring team’s to collect. Metaview then drafts the scorecard from that conversation, and the interviewer corrects the draft and submits it with their own ratings.
Metaview captures every spoken word in that call, so the draft starts from what this candidate said in this interview. A draft can’t stop comparing in an interviewer’s head, though, so I’d still ask interviewers to submit each scorecard before their next interview for the role.
Good interviewers know they are contributing to a hiring decision. Bad interviewers believe they are making a hiring decision.”
An interviewer who thinks the hiring decision is theirs will pick a winner from the day, and picking a winner is a comparison. One who sees the scorecard as a contribution has a reason to rate this candidate against the rubric and leave the choosing to the decision.
For this method, I’d ask Reports a question about your own interview data: how often a role’s interviews touch each competency on its scorecard. The example below shows that for one role’s sales screens, one bar per competency:
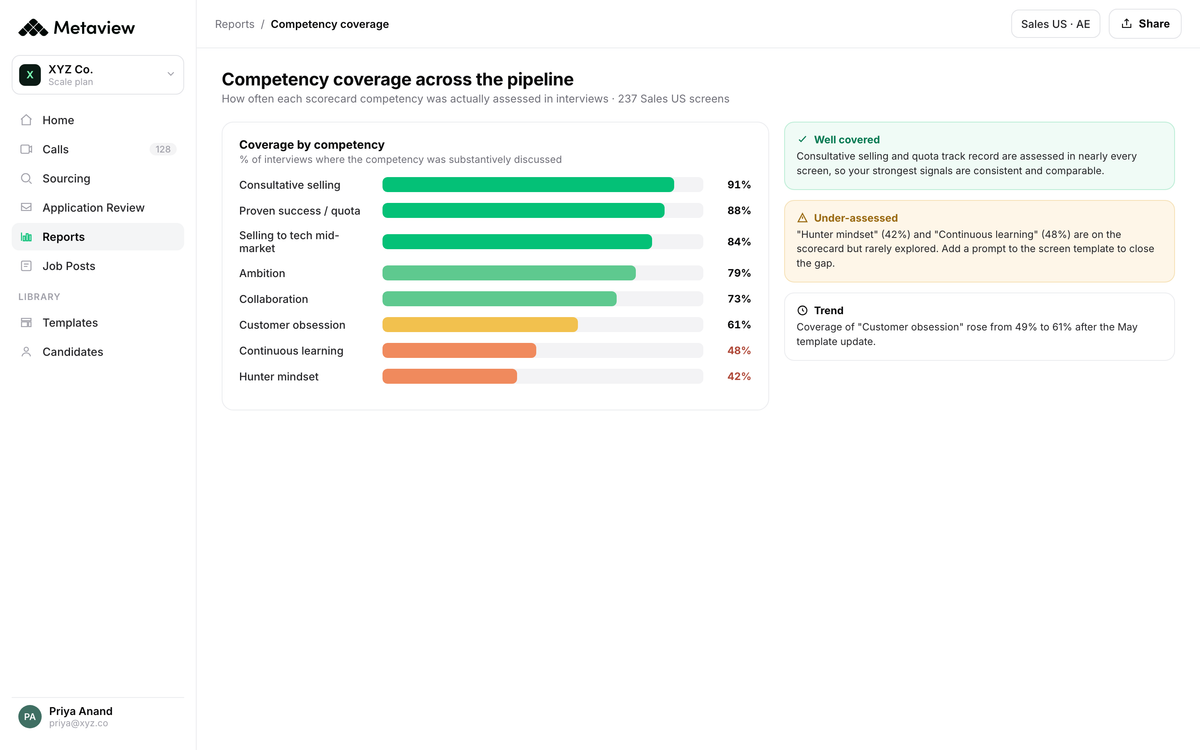
- 1The “Coverage by competency” chart, one bar for each competency on the role’s scorecard.
- 2“Hunter mindset,” the competency discussed least often in these screens.
I’d read a report like this from the bottom. Where interviews rarely touched a competency, a rating for it has little to stand on except the interviewer’s overall impression, and that impression is where I’d expect the candidate before to have the most pull. So before trusting anyone’s rating on “Hunter mindset” in a slate like this one, I’d check what that candidate’s scorecard says they were asked about it.
Check whether the queue is still setting the score.
The method is working when a candidate’s rating no longer depends on who came before them. Whoever owns the debrief for a role can test that on its next slate, with a spreadsheet of the submitted scorecards:
- Sort each interviewer’s scorecards for the role by interview order and find the candidate straight after that interviewer’s highest rating. Compare those follow-on ratings with the same interviewer’s other ratings for the role. If they sit lower across several interviewers, the standout may have become the bar, so start with the one-candidate-open rule, and read the next slate the same way before drawing more from a sample this small.
- Read the rating comments for comparatives that name another candidate. If they keep turning up, the rewrite isn’t being asked for, so make it the first question of every debrief.
- Compare when each scorecard was submitted with when its interviewer next met a candidate for the same role. A scorecard submitted after that later interview was written once the interviewer had met someone else for the role, so book the gap before anything else.
- Check whether the rubric changed partway through the slate, and whether the earlier candidates were re-read against the new version. If they weren’t, two bars decided one role, so re-read them before the decision.
When the follow-on ratings look like everyone else’s, the rubric sets the bar again, and the queue goes back to being the order the interviews happened to be booked in.
Ask how often a role’s interviews reach each rubric line.
See Reports answer that from your team’s interview data, so you know which ratings rest on the least conversation.
Frequently asked.
Does contrast bias affect phone screens as well as final rounds?
Yes, and screens are often where it runs longest, because a recruiter can take several first calls for one role in a row. The rule works the same way there: write up each screen and its rating before the next call for that role starts.
Is contrast bias the same as the halo effect?
The halo effect lets one strong trait color the rest of a candidate’s own ratings, while contrast bias borrows the measure from someone else, usually the candidate before. Halo is checked by rating each competency on its own evidence, and contrast by keeping other candidates out of view while you score.
Should interview order be randomized to avoid contrast bias?
A random order spreads the effect around without removing it, since every candidate except the first still follows somebody. I’d schedule around what suits candidates and interviewers, and put the effort into how and when each rating gets written.
Does scoring straight after the interview make the rating less considered?
A rating written straight after the interview draws on the freshest notes, and the interviewer can still revise it before the debrief if rereading those notes changes their view. I’d avoid revising it after meeting another candidate, because that brings the comparison back in.
How do you raise contrast bias with an interviewer without it sounding like blame?
Talk about the schedule and the form rather than the person. Every interviewer compares when two candidates sit in their head at once, so the conversation is about keeping that from happening, and asking for the rubric version of a comparative is a request about the note.
