Most candidate quality problems start at the profile. Sourcing for a hard role means reading hundreds of profiles, and the reviewer is asked to judge each one on things a profile cannot show, such as how the person explains their own work or why they want this job.
So the reviewer judges what the profile does show. A well-known employer and a senior title start standing in for the bar, and the shortlist looks strong right up to the first calls. Meanwhile the strong candidate with a plain profile never gets a call at all.
Before anyone reads a profile, I’d split the bar in two. Judge each profile only on what it can show, and turn everything else into questions the first call asks every candidate. With the bar split that way, you can identify top-notch profiles at scale, because the reviewer on profile four hundred is reading for the same lines as the reviewer on profile four.
Split the bar into what a profile can show.
Start from the bar the hiring manager agreed at intake, and sort each line of it by where the evidence for it can be found. Some of it sits on a profile, and the rest only comes out when someone asks.
| Line of the bar | What a profile can show | What waits for the first call |
|---|---|---|
| Has done this kind of work before | Named projects, and the size of team or budget behind them | Which decisions on those projects were theirs |
| Can explain the reasoning behind their work | Published writing or talks, where they exist | How they talk through a decision they would now make differently |
| Wants this role | Very little beyond what the application says | Why this role, and why they would move now |
| Will work well with this team | Almost nothing | How they describe a disagreement with a past manager |
Sorted this way, the bar stops a reviewer marking a profile down for something no profile could show, and it hands the first call its list of questions. I’d keep the middle column to four or five lines and make every one of them something you can point at on the profile, such as a named project or the size of a team.
Name the stand-ins your reviewers fall back on.
Reading at volume, a reviewer reaches for whatever is quickest to spot, and that is rarely anything the bar asks for. I think the bar only holds if the usual stand-ins are written down beside it:
- A well-known employer, which says where someone worked and little about what they did there.
- A senior title, which can mean a team of two at a startup or a team of forty at a large company.
- Years of experience as a count, which measures time rather than the work done in it.
- Polished writing, which shows the profile was edited well.
Each of them tells you something, so I wouldn’t ban them. The rule I’d agree with the hiring manager is that no stand-in decides alone: one can break a tie between two profiles that meet the same lines, and none can carry a profile onto the shortlist or keep one off it.
If you want the longer list of shortcuts that creep into screening, this guide to candidate screening bias covers where each one enters the process.
Test the bar on two reviewers before the queue.
A written bar can still be read two ways, and the quickest way to find the vague line is to have two people use it. Before the queue runs at full volume, give two reviewers the same twenty profiles and the middle column of the table. Each gives every profile a yes or a no with a one-line reason, without seeing the other’s answers.
Then compare the answers. Where the two reviewers differ, their reasons usually point at one line of the bar read two ways, and that is the line to rewrite. I’d rewrite it until both give the same answers on those profiles, then try the new version on twenty they haven’t seen. Agreement only shows that the bar reads one way, and only the first calls can tell you whether it is the right bar.
Skip this, and the queue runs on each reviewer’s private bar, so whether a profile reaches the shortlist depends on who opened it.
Turn the rest of the bar into first-call questions.
The right-hand column of the table is now the list of what the first call has to find out. Write one question for each line, and give every candidate the same questions once they pass the profile read. Ask each question about something the candidate has already done, because a past project is something they can describe in detail and you can follow up on.
- For decisions they owned: “Which part of that project would have gone differently without you?”
- For their reasoning: “Tell me about a decision on that work you’d make differently now.”
- For wanting the role: “What would make you turn this role down?”
- For working with the team: “Tell me about a time you disagreed with a manager, and how it ended.”
Keep the list short enough to finish in the time you have. A call that runs out of time leaves different lines blank for different candidates, and the comparison later has nothing to compare.
If you’re writing those questions from scratch, this guide to competency-based interviewing covers how to word questions that ask for evidence.
Compare candidates only on what each one was asked.
Before a debrief settles on one candidate as stronger on some part of the bar, check that both were asked about it. A candidate with nothing recorded against a line hasn’t been tested on it, and the blank says nothing about how they would have answered.
So lay the shortlist out against the lines of the bar and mark which lines each candidate’s calls covered. Where a line is blank for one candidate and answered for another, close the gap first, with a short follow-up call or a question added to the next interview, and compare after that.
Without this check, a candidate whose first call ran short loses to whoever was asked more questions. If the debrief keeps drifting toward whoever impressed the room most, this guide to interviewer bias walks through ways to pull it back to the evidence.
Where Metaview fits in sourcing for candidate quality.
Two parts of this method get slow at volume: the first read of a large pile of applications, and a record of each first call good enough to compare later. Application Review takes that first read for inbound applications, and the Notetaker keeps the record of each call. The bar, and every decision made against it, stays with your team.
Applications reach Application Review from your applicant tracking system through Metaview’s integrations, and Application Review reads every one against the role’s written bar, which it keeps as an ideal candidate profile (ICP). It drafts the ICP from the job description and any context you add, and a recruiter edits and approves it before Application Review reads a single application against it. I’d write the profile column into that ICP and leave the first-call column out, since no application can answer it.
Each application then goes into one of four fit buckets, from Great to Poor, with the reasoning beside it. Application Review gives no numerical score, and a recruiter decides who progresses and who is rejected. If the two-reviewer test used applications, set Application Review’s reasoning on those twenty beside your reviewers’ answers. Where the reasoning leans on a different line than they did, that line of the ICP needs rewriting. Edit it and approve the change, and the candidate list in Application Review then re-evaluates against the new version.
Application Review represents a fundamental shift in how AI should work in recruiting, not as a replacement for human judgment, but as infrastructure that handles operational scale while keeping recruiters focused on what matters: connection and decision-making.”
I’d spend the recruiter’s time on the applications near the bar, checking the reasoning where a line of the ICP is most likely to be read two ways.
Sourced profiles work differently. AI Sourcing searches from a single prompt you write in plain language, reaching the open web as well as people already in your connected applicant tracking system or in past Metaview conversations. Each person the sourcing agent brings back comes with its reasoning, and it neither contacts nor assesses anyone by itself, so the read against the bar stays yours. I’d write the prompt from those same profile lines and check each line of reasoning against it before a name goes on the shortlist.
Reports works over your team’s own interview data, inside Metaview or from an AI assistant hooked up to it. The example report below sets four candidates’ interviews against four competencies and counts the questions asked in each:
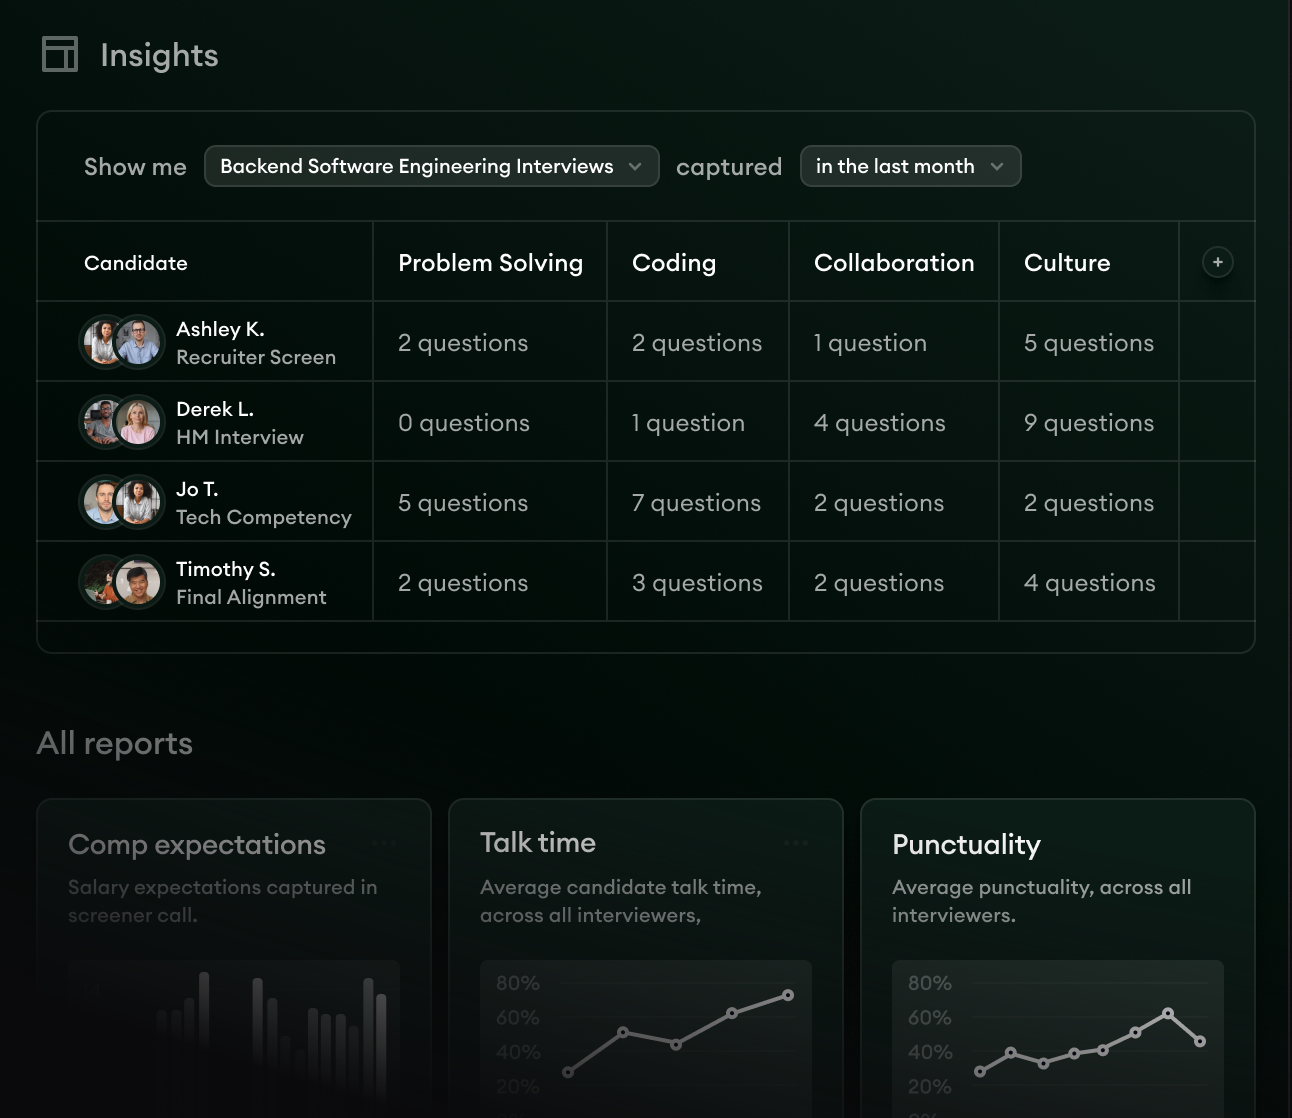
- 1Each row pairs a candidate with the interview they had, from “Recruiter Screen” to “Final Alignment.”
- 2“Jo T.” was asked “7 questions” on coding in a “Tech Competency” interview.
- 3“Derek L.” was asked “9 questions” on culture in a hiring manager interview, and “1 question” on coding.
On coding, “Jo T.” answered seven questions and “Derek L.” answered one. A debrief that ranks them on coding is weighing a full technical interview against a single question, so I’d ask “Derek L.” about coding before anyone compares the two.
For the first calls themselves, the Metaview Notetaker can sit in as a visible participant, as long as everyone in the conversation has agreed to recording, which your team arranges under its own policy. It records the call and transcribes it. Afterwards the notes come back structured, laid out by the template your team chose for first calls.
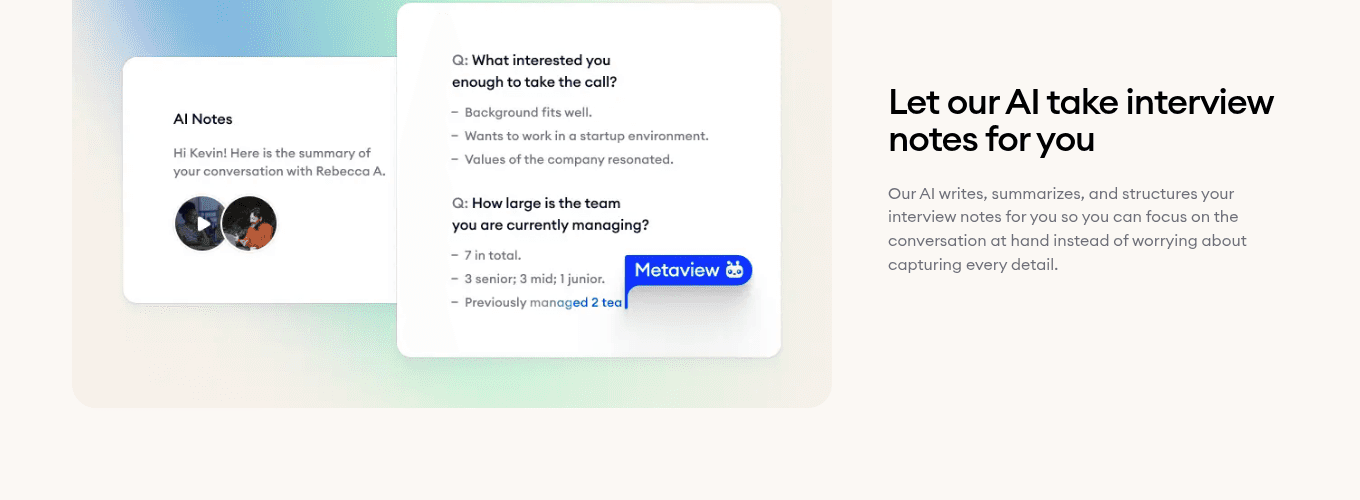
- 1The “AI Notes” card, a summary of one conversation with a candidate.
- 2The candidate’s answers grouped under “What interested you enough to take the call?”
- 3Answers under “How large is the team you are currently managing?” starting with “7 in total.”
Metaview captures every spoken word of a first call, which means that before a debrief compares two candidates on one part of the bar, someone can check whether each of them was asked about it at all.
Templates are also what keep notes comparable across a large pool. Jessica DeOliveira, Managing Director, Strategic Initiatives & Client Delivery at the executive search firm Raines International, on the templates her firm uses: “The custom templates give us a consistent and rigorous way to compare apples with apples across a large number of individuals.” For a team sourcing at volume, I’d make the template’s headings the lines of the first-call column, so every candidate’s notes come back answering the same questions.
Check the bar after every round of first calls.
The method is working when the profile read keeps lining up with what the first calls find. After each round of calls, I’d run four checks, each pointing at what to fix first:
- Profiles that passed keep failing the same first-call question. That line belongs in the profile column, or the profile read is leaning on a stand-in, so look first at what those profiles had in common.
- Two reviewers still disagree on the same kind of profile. Rewrite the line they read differently before the queue grows any further.
- First calls come back with the same lines blank. The question list is longer than the call, so cut it to the lines that change the decision.
- The shortlist looks like the last person you hired. A stand-in is carrying the read, so rerun the two-reviewer test on profiles that look nothing like that hire.
On the next role, build the shortlist only from profiles that met every line a profile can show, then put the same first-call questions to each of those candidates. Do both, and the bar holds at volume: a top-notch profile means the same thing on the last read of the week as on the first.
Keep the bar steady across hundreds of sourced profiles.
Watch AI Sourcing work an open role from a plain-language prompt, with the agent’s reasoning beside every person it finds for your team to read against the bar.
Frequently asked.
When is the bar ready for the full queue?
When two reviewers give the same answer on nearly every profile in the test set. If they split on more than a handful, rewrite the lines behind the splits and test again on profiles neither has seen, because reviewers who reread the same set start remembering each other’s answers.
What if a must-have can only be checked in a conversation?
Put it at the top of the first-call list, and let the profile read pass anyone who could plausibly meet it. A profile read that guesses at it turns away people who meet the requirement and never wrote it down.
Should applications written with AI be marked down?
Read them against the same lines as any other profile. Polished wording tells you little in either direction, so it should neither lift a profile nor sink one. On the first call you find out whether the person can talk through the work the profile describes.
Does splitting the bar work for high-volume roles?
Yes, with a shorter profile column. For a role with hundreds of applicants I’d keep two or three lines a reader can check in seconds, and let the first call carry more of the bar.
How do you keep the bar the same across several recruiters on one role?
Give every recruiter the same written bar and the same list of stand-ins, and rerun the two-reviewer test whenever someone new joins the role. Swapping a few profiles between recruiters each month and comparing reasons keeps the readings close.
